Buffers in Node.js
Buffers are a fixed chunk of memory that stores raw binary data. They are used to store binary data such as images, videos, audio, etc.
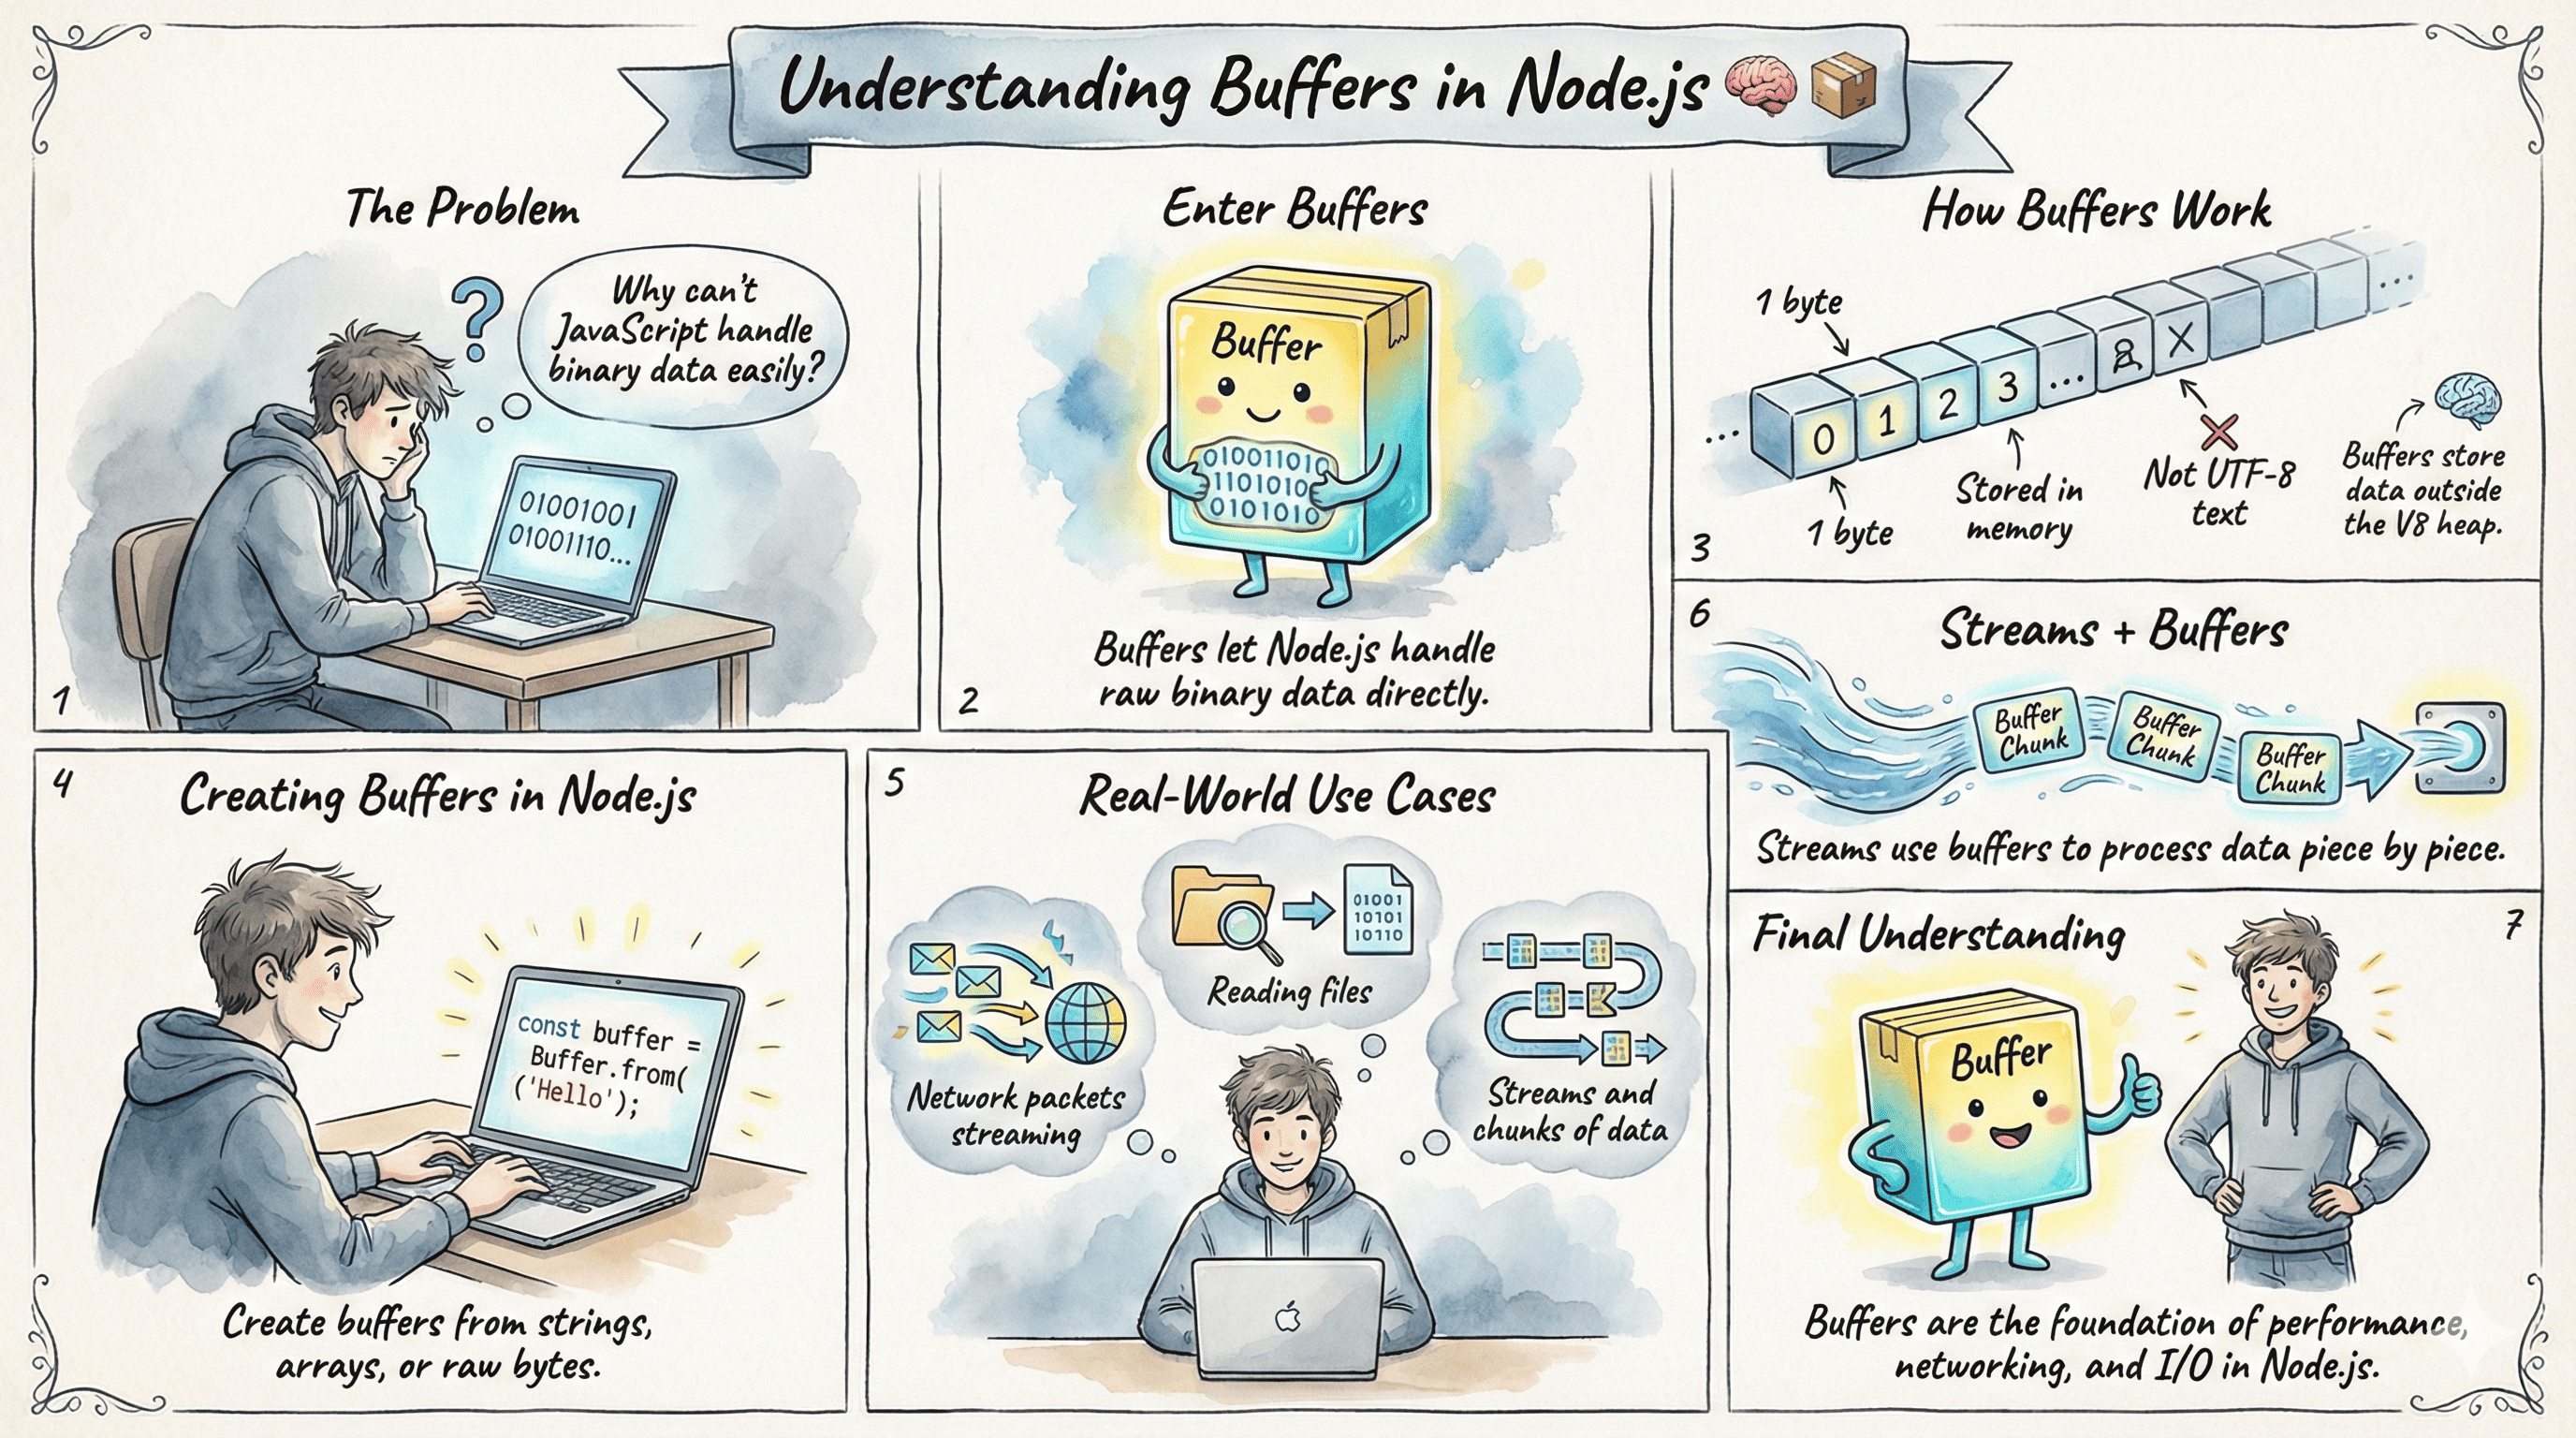
In Node.js, a Buffer is a specialized object used to handle raw binary data. Think of it as a fixed-size chunk of memory allocated outside the V8 JavaScript engine's heap.
Since JavaScript was originally designed to handle strings (Unicode), Buffers were introduced to let developers interact with TCP streams, file systems, and binary structures directly.
If you’ve worked with Node.js for more than five minutes, you’ve seen the word Buffer.
It shows up when you:
- read a file
- upload an image
- stream a video
- handle HTTP requests
- work with encryption
- talk to Redis, Kafka, or sockets
And yet... most people use Buffers without ever truly understanding them.
This blog fixes that.
By the end of this article:
- Buffers will feel obvious, not magical
- You’ll know why Node.js needed them
- You’ll understand what’s actually happening in memory
- And you’ll be able to explain Buffers so clearly that interviewers will stop you mid-sentence and say: “Okay, that’s enough - you clearly get it.”
Let’s start from first principles.
Why do Buffers even exist?
Imagine this situation.
You’re sending a photo from your phone to a friend.
Pause for a second and ask yourself:
Is that photo…
- letters like
A B C? No - words like
"hello"? No
Of course not.
A photo is raw data.
Just a massive chunk of numbers.
And this is the first uncomfortable truth of computing:
Computers do not understand
English, Hindi, emojis, or JavaScript strings.
They understand exactly one thing:
numbers
More specifically: 0s and 1s
Those 0s and 1s are called binary data.
Everything else - text, images, videos, PDFs - is just a human-friendly interpretation layered on top.
What is Binary Data? (No jargon, promise)
Binary data simply means:
- Information represented using 0s and 1s (These are known as bits)
- Because computers are electrical
- And electricity has two stable states: on / off
That’s it.
For example:
A->01000001B->01000010- A photo -> millions of these bits
- A video -> billions
So when Node.js reads:
- a file from disk
- data from a network socket
- an uploaded image
- an audio stream
It does not read “text”.
It reads binary data first.
Always.
Why normal JavaScript strings are NOT enough
At this point, a fair question is:
“Why can’t we just use JavaScript strings?”
Because strings are designed for text, not raw bytes.
const text = "hello";
This works beautifully for:
- UI text
- JSON
- logs
- small messages
But it becomes dangerous when used for:
- images
- videos
- PDFs
- audio
- encrypted data
- compressed data
Why?
Because strings:
- apply character encoding
- use more memory
- can silently corrupt binary data
If you try to treat raw bytes as text, you’re basically asking:
“Hey JavaScript, please guess what these numbers mean.”
That guessing is where bugs are born.
Node.js needed something lower-level, predictable, and fast.
That “something” is Buffer.
What is a Buffer? (The core idea)
Here’s the cleanest definition:
A Buffer is a fixed chunk of memory that stores raw binary data.
That’s it.
No magic.
Think of it like this:
- Buffer = a box in memory
- Inside the box = numbers
- Each number = one byte
If it helps, imagine an egg tray 🥚:
- Each slot holds exactly one egg
- You can’t stretch a slot
- You can’t store text in it
- You only store raw values
That’s a Buffer.
What is a Byte? (This word matters)
A bit is a single 0 or 1.
A byte is:
8 bits
So:
00000000-> 011111111-> 255
This means:
One byte can store a number between 0 and 255
And here’s the key connection:
A Buffer is simply a sequence of bytes
So when you see:
Buffer.alloc(5);
It literally means:
“Give me 5 bytes of memory.”
Which looks like:
[ 0, 0, 0, 0, 0 ]
Creating a Buffer (the right way)
Create an empty buffer
const buf = Buffer.alloc(4);
What just happened?
- Node allocated 4 bytes
- Each byte is initialized to
0 - Memory is clean and safe
Internally, it’s:
[ 0, 0, 0, 0 ]
Create a buffer from text
const buf = Buffer.from("ABC");
Now something interesting happens.
Each character is converted into a number:
A-> 65B-> 66C-> 67
So the buffer becomes:
[ 65, 66, 67 ]
Important realization:
The buffer does not store letters
It stores numbers that represent letters
Reading from a Buffer
const buf = Buffer.from("Hi");
console.log(buf);
Output:
<Buffer 48 69>
Why 48 69?
Because Node prints buffers in hexadecimal by default.
H-> 72 ->0x48i-> 105 ->0x69
This is your first visual proof that:
Buffers store numbers - not characters
Writing into a Buffer manually
Let’s flip things around.
const buf = Buffer.alloc(3);

buf[0] = 65;
buf[1] = 66;
buf[2] = 67;

console.log(buf.toString());
Output:
ABC
What happened?
- You stored numbers
- Then told Node: “Interpret these numbers as text”
This is crucial:
Buffers don’t care what the numbers mean
You decide how to interpret them
Encoding (Very important, very misunderstood)
Encoding answers one question:
“How do numbers become characters?”
Common encodings you’ll see:
utf8(default, most common)asciihexbase64
Example:
Buffer.from("hello", "utf8");
Buffer.from("hello", "ascii");
Different encoding -> different byte patterns.
That’s why encoding mistakes cause:
- broken text
- corrupted files
- unreadable data
Buffers give you control over encoding instead of guessing.
Where Buffers appear in real life (even if you don’t notice)
You don’t manually create Buffers every day - but Node uses them everywhere.
Examples:
fs.readFile("photo.png", (err, data) => {
  // data is a Buffer
});
Other places:
- HTTP request bodies
- File uploads
- Video streaming
- TCP sockets
- Encryption libraries
- Redis / Kafka messages
Anywhere Node talks to the outside world, it speaks in Buffers.
Why interviewers care so much about Buffers
They’re not testing trivia.
They want to know if you understand:
- how Node handles I/O
- how memory works
- why Node is fast
- why streams exist
Classic interview question:
“What happens if you read a large file as a string?”
Correct answer:
- The entire file loads into memory
- The process can slow down or crash
- Buffers + streams solve this problem
(We’ll cover streams next time.)
Buffer vs Array (classic trap)
| Feature | Buffer | Array |
|---|---|---|
| Stores raw binary | Yes | No |
| Fixed size | Yes | No |
| Memory efficient | Yes | No |
| Used in I/O | Yes | No |
| Encoding-aware | Yes | No |
Buffers are low-level by design.
Arrays are high-level and flexible.
Different tools. Different jobs.
The one rule to remember forever
If you remember nothing else, remember this:
Node.js talks to the outside world using Buffers.
Files.
Network.
Streams.
Sockets.
All buffers.